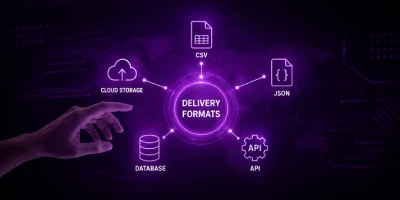
How We Deliver It
Our Amazon Scraping Capabilities
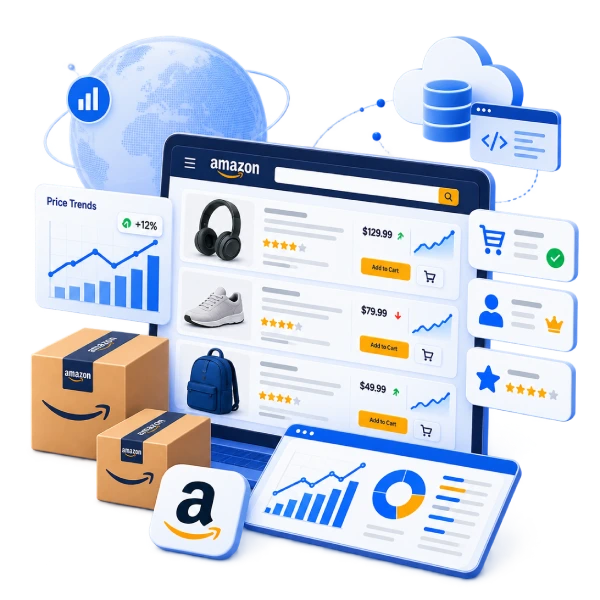
Amazon data scraping at production scale needs more than a script — it needs infrastructure. Here's what powers every engagement.
Scale
Large-Scale Crawling
Crawlers built to work across millions of ASINs and entire category trees without falling over under volume.
Cadence
Scheduled Scraping
Recurring jobs run hourly, daily, or weekly, matched to how fast your category's prices and stock actually move.
Speed
Real-Time Extraction
Near-instant refresh cycles for pricing and Buy Box tracking where minutes matter to your team's decisions.
Integration
API Integration
Scraped data can be exposed through a dedicated endpoint so your internal systems pull it on demand.
Infrastructure
Cloud Deployment
Crawlers run on scalable cloud infrastructure that expands or contracts with your project's volume.
Reach
Global Coverage
Coverage across Amazon marketplaces in North America, Europe, and Asia-Pacific, with locale-aware parsing.
Network
Proxy Infrastructure
Rotating residential and datacenter proxies keep requests distributed and extraction reliable at scale.
Resilience
CAPTCHA Handling
Automated CAPTCHA-solving and human-like request pacing keep pipelines running through anti-bot defenses.